This is a planning lower bound plus your manual allowances. It does not certify that a particular model will load, fit entirely in VRAM or run at a useful speed.
Method and limits
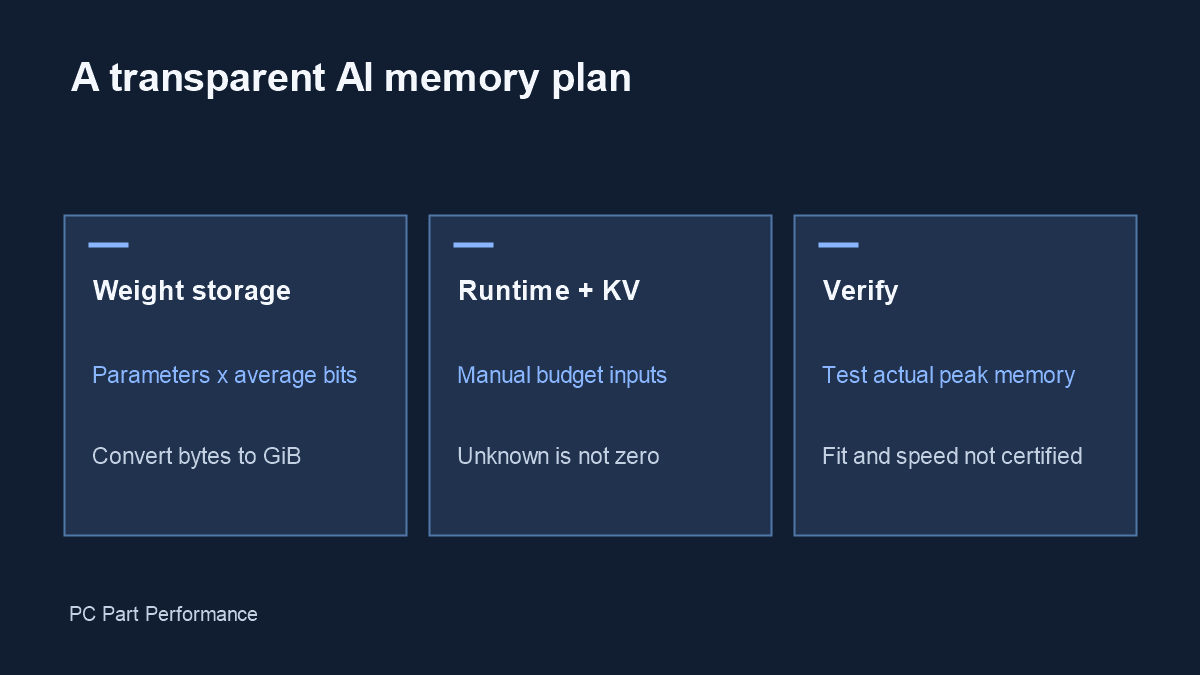
Formula: billions of parameters × 1,000,000,000 × average bits ÷ 8 ÷ 2³⁰. Real model files include format details and can mix storage types. Their measured size is stronger evidence than the simplified weight calculation.
Enter runtime and cache budgets from the configuration you plan to use. Empty values are unresolved, not zero. Context length, concurrency and cache format matter, so this tool does not infer the cache from token count alone.
Confirm software support and record actual peak memory and response speed with a representative prompt before purchasing hardware. CPU offloading, GPU memory and system RAM are separate resources, not a single guaranteed pool.